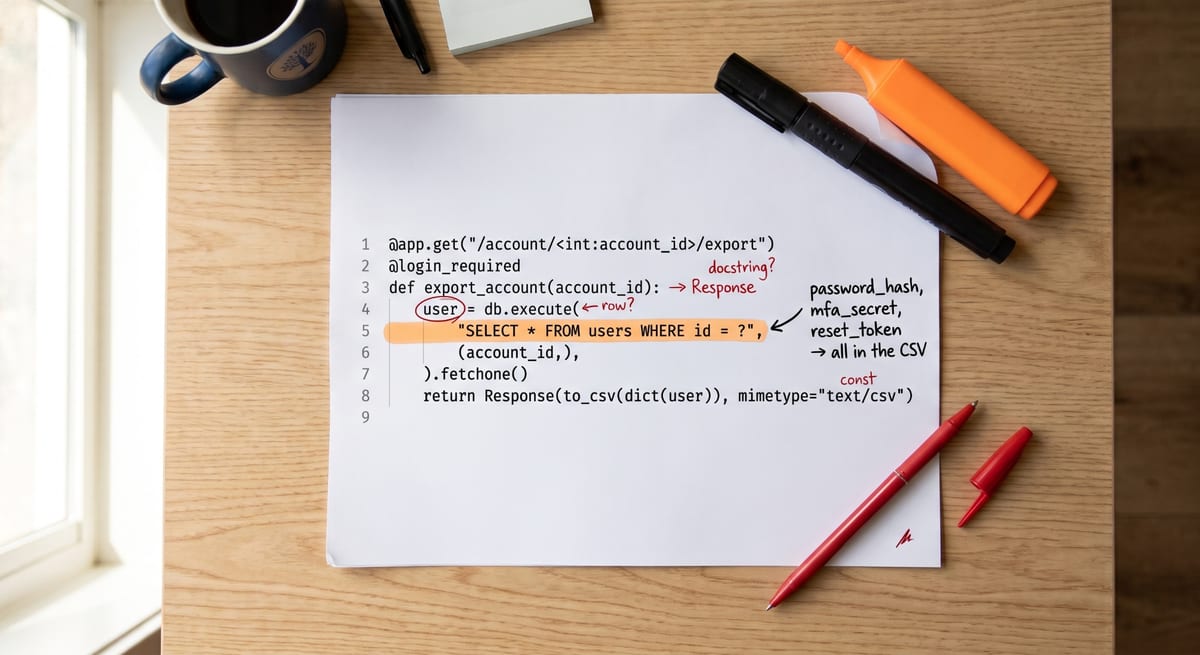
The ticket said: "Users should be able to export their data."
An engineer on a team we worked with pasted that into an agent, more or less verbatim, and got back a CSV export button on the account settings page. It worked. It shipped. Within a month, support started getting tickets from users who wanted their data in a format their new tool could actually import, from users who had two accounts and wanted one export covering both, and from one enterprise customer who needed the export to exclude a specific data category for a contractual reason nobody on the engineering team had ever heard of.
None of that was in the ticket. None of it was in the prompt either, because the prompt was the ticket.
Those were the problems people could see. The ones that didn't arrive as support tickets were worse.
What the one-line prompt actually produced
When we read the code properly, after the support tickets had made everyone curious, it looked fine. It was also doing a long list of things nobody had decided.
The export query started from the users table and took every column. That included the password hash, the MFA secret and the password reset token. It joined the sessions table and the API keys table, because "their data" plausibly covered both, so the file also contained live credentials. Anyone holding the export could log in as that user.
It joined the messages table on conversation rather than on author, so a user's export contained every message other people had sent them. It included the support notes field, which is where the support team writes things like "difficult customer, do not offer discounts." It included rows the user had deleted, because deletion was soft and the query never filtered on it.
The endpoint took the account ID as a URL parameter and checked that the caller was logged in, not that the caller owned that account. Change the number, export someone else.
It asked for no re-authentication, so a stolen session was one click away from a complete dossier. It sent no notification. It emailed the link to whatever address was on the account at that moment, so an attacker who changed the email first received the export. The link never expired.
Then there was the load, and that part did not wait for anyone to read the code.
The export ran inside the web request: load everything, build the file, store it, email the link. For a typical account that took two seconds. For a customer who had used the product daily for nine years, with several gigabytes of attachments, it never finished. The load balancer gave up at sixty seconds, but the server kept working. The user saw an error and clicked again, and now two copies were running, because nothing stopped a second export starting while the first was still going.
Each copy fetched the account one record at a time, one query per row, which for nine years of activity meant millions of round trips to the database. Each held a single transaction open on the primary for the entire read. A long-open transaction forces the database to keep old versions of every row it might still need to show, so the routine cleanup of those versions stalls and the whole database gradually slows, for every user, not just the one exporting. And each copy built the complete file in memory until the process ran out and was killed, taking down every other request that process happened to be serving.
In the first week, two long-time users trying the same thing on the same evening were enough to page someone.
The first fix was the obvious one: move the export into a background job. That made the web requests fast again, and it created a fresh set of problems nobody had specified either. There was no limit on how many exports could run at once, so when a product newsletter mentioned the feature a few weeks later, a few hundred users tried it within the same hour and every background worker on the platform filled up with exports. Password reset emails and billing jobs sat in the same queue behind them for most of an afternoon. Failed jobs retried from the beginning, so the largest accounts failed, restarted and failed again, holding a worker each time. And every attempt wrote its temporary file to the job server's local disk and never deleted it, until the disk filled and the server stopped.
The agent did nothing unusual. Every one of these is the statistically common way to write an export, which is exactly the problem. None of it looked wrong in a quick review. It was clean, readable code built on decisions nobody had made, and a small test account exercised none of them.
A requirement is not a specification
Part 6 made the case that a requirement and a specification are different objects. This article is about producing the second one.
"Users should be able to export their data" is a requirement. It states a desired outcome. It says nothing about format, scope, edge cases, what "their data" includes, or what the feature must never do to the rest of the system.
A specification answers the questions a requirement leaves open. Not all of them, not exhaustively, but the ones that change what gets built.
The Enabling Structures framework we've written about elsewhere calls this the specification gate: a mandatory step before any AI generation begins, where a behavioral spec and its acceptance criteria get written down before a single line of code exists. Teams that skip this step do not get less work. They get the same work, done twice, with a production incident in between.
The gate does not require an exhaustive document. It requires the five things Part 6 said a specification has and a requirement does not: valid inputs, expected outputs, failure definition, performance and scale assumptions, and dependency behavior. It also requires the two things Part 6 noticed sit outside those five: the scope, meaning the unit you are working with, and what you are deliberately not building. And one more, which turns the whole thing into something testable: what done means, in terms someone else could verify.
The export ticket gestures at one expected output ("their data") and says nothing about the rest.
There is a catch in how those categories get filled in. Most of us fill them in for the user in front of the feature. They also have to be filled in for the data behind it and the system around it. Valid inputs covers a user clicking a button. It also covers a stolen session and someone else's account ID typed into the URL. Expected outputs covers the columns a user wants. It also covers the column somebody adds to the schema next year. Performance and scale covers one user waiting for a file. It also covers a nine-year account, and a few hundred users clicking the same button in the same hour.
Rewriting the ticket
Here is what a specification for the same feature looks like once those categories get filled in, including the parts the first version never raised.
Scope: One account per export, for the account the requester is logged into.
Valid inputs: The account is taken from the session, never from a request parameter. The user must re-enter their password or pass MFA within the ten minutes before requesting. One export per user at a time; a second request while one is running is rejected with a message, not silently queued or silently ignored.
Expected outputs (format): A ZIP containing one file per data category, because the tools people move their data into import one kind of record at a time, and because a category can then be left out for a customer whose contract excludes it without touching the rest. CSV for flat categories, UTF-8 with a byte order mark so spreadsheet tools read accented characters correctly; JSON for nested ones. Attachments the user uploaded go in as the original files, in a folder of their own. Any CSV cell beginning with =, +, - or @ is escaped, so a user's own text cannot run as a formula when the file is opened.
Expected outputs (contents): The contents are an allowlist: profile fields the user entered, their activity history, content and attachments they authored, and billing invoices with bank account numbers masked to the last four digits. Any field not on that list is excluded, including fields added to the schema after this ships. Explicitly excluded: credentials and secrets of any kind (password hashes, MFA secrets, reset and verification tokens, sessions, API keys), content authored by other users, and any category excluded by the customer's contract. Internal fields such as risk scores and support notes, and records the user has deleted, are not in this export either; a user who asks for them goes through the formal data access process, which legal handles separately.
Expected outputs (delivery): A download link to the registered address, and a notification to the previous address as well if it changed in the last seven days. The download requires the same logged-in user, the link expires after 24 hours, and the file is deleted after seven days. Every export request goes into the audit log. Neither the file contents nor the link are ever written to application logs. Most accounts complete within five minutes of starting; the largest can take up to an hour. When the export pool is full, requests wait in a queue, and the user sees their place in it and the likely wait before they commit.
Failure definition: A job that fails partway resumes from the last completed category rather than starting again. After three failed attempts the user is notified and no partial file is delivered. A job that has been running for two hours, not counting time spent waiting in the queue, is treated as failed and its worker released.
Performance and scale assumptions: The largest real account is nine years of activity and several gigabytes of attachments; everything below is sized for that account, not the average one. Exports run as background jobs on their own worker pool, capped at five concurrent jobs across the platform, so they can never starve password resets or billing. They read in batches, never one record at a time, using keyset pagination rather than offsets. They stream straight to object storage instead of building the file in memory or on local disk. No transaction stays open longer than a single batch.
Dependency behavior: Exports read from a replica, never the primary. If the replica is lagging, the export reflects data up to a few minutes old, and the confirmation says so. If the email provider is down, the file is still available from the settings page and the email is retried. If object storage is unavailable, the job waits and retries; it never falls back to local disk.
Not building now: Multi-account merging, organisation-wide exports by admins, and exports for deleted or locked accounts. Noted explicitly, rather than left to be discovered later.
Done means: A user can trigger an export from settings and receive a file that opens cleanly. Verified against a test account built to the size of the largest real one, running alongside four other exports so the pool is full, with primary database latency and password reset delivery times unchanged throughout.
Look at where most of that specification goes. The ticket asked for a feature. Most of the spec is about what the feature must not contain and what it must not do to everything around it.
There is also no heading called Security, and that is deliberate. Security is not a category; it runs through every one of them. Who may ask is a valid input. What the file may contain is an expected output. Where the link may go, and what gets logged, belong to delivery. A spec that puts security in its own box at the end tends to treat it as a checklist item. Filling in the five categories honestly forces it into every decision instead.
The single most important line is the contents are an allowlist. A list of fields to exclude is correct on the day it is written and wrong the day someone adds a new sensitive column. A list of fields to include stays correct by default. The agent will almost always produce neither. It takes every column, and the best a reviewer usually adds afterwards is a list of exclusions, because "export everything except the obvious secrets" is what most export code looks like.
Every one of those decisions was available before the first line of code. None of it required knowing anything an engineer with domain context didn't already have, or couldn't get by asking one question. It required asking the questions and writing the answers down, instead of generating from the sentence that skipped past them.
Why this got harder to skip
Before agents, writing an incomplete spec was survivable, because the engineer building it filled the gaps as they went. They hit the multi-account question three files into the implementation, thought about it for a minute, and made a call. They wrote the query by hand and noticed the password hash in the column list. They ran it against their own long-lived test account and watched it take four minutes. The mental model was under construction the whole time, so the gaps got caught close to where they mattered.
An agent does not fill gaps by thinking about your business. It fills gaps by pattern-matching to whatever is statistically common for "data export" in its training data, and it does this instantly and silently. You do not see the moment the gap got filled, because there was no moment. The combined file, the credentials in the export, the account ID in the URL, the one-query-per-row loop on the primary; all of it arrives already decided, wrapped in code that runs and passes a quick smoke test on a small account.
The gaps did not go away when the friction of typing every line went away. The friction was doing more work than it looked like it was doing.
What this costs, and what it saves
Writing the second version of that spec took about forty minutes longer than pasting the ticket. It is a real cost, and on a busy day it is tempting to skip it, especially when the agent is fast enough that just seeing what comes back feels cheaper than thinking first.
It is not cheaper. The team that shipped the one-line version spent days handling the support tickets and patching category exclusion under contractual pressure. Every account that had ever been exported, by its owner or by anyone else, had its sessions and API keys invalidated, its password reset forced and its MFA re-enrolled, because there was no way to know where those files had gone. And because anyone could have exported anyone else's account by changing one number, legal had to treat the whole thing as a possible data breach, on a regulator's 72-hour notification clock. Meanwhile they moved the export into a background job, which fixed the timeouts and then held up password resets for an afternoon, and rebuilt it properly the week after.
The forty minutes is not overhead added to the work. It is the work, moved earlier, where it is forty minutes instead of a month of cleanup.
What this means for you
Before you next open an agent against a real ticket, try rewriting it against the five categories above, plus scope, what you are not building, and what done means. Do it on paper, before you type anything into the tool. Fill each category in for the data and the system as well as the user. Most tickets leave several of them empty. That gap is not a flaw in whoever wrote the ticket. It is the normal state of a requirement, and turning it into a specification was always your job; it just used to happen invisibly, while you typed the code yourself.
The next article is about a faster version of this same check: a sixty-second exercise for finding what's missing from any requirement before you build from it.
© Gabor Mayer. Licensed under Creative Commons Attribution 4.0 (CC BY 4.0). Free to share and adapt with attribution.